

It was Sam. Yes, really.
No, it wasn’t a PR stunt. Just negligence.
Yes, they spun it as capability instead of liability.
No, it wasn’t China. China (GLM) actually helped.
If you’re in a rush, this is the summary of the entire piece. If you’re not in a rush, maybe because you’re roasting on a beach somewhere, the long version is coming.
The Victim Side: What Happened to HuggingFace?
On 16/Jul, HuggingFace published a very alarming security incident disclosure, detailing a cyber attack driven end-to-end by an autonomous AI agent.
We identified unauthorized access to a limited set of internal datasets and to several credentials used by our services.
We don’t have to dig much to understand what happened, HuggingFace shared the outlines of the attack:
A malicious dataset abused two code-execution paths in our dataset processing (a remote-code dataset loader and a template-injection in a dataset configuration) to run code on a processing worker. From there, the actor escalated to node-level access, harvested cloud and cluster credentials, and moved laterally into several internal clusters over a weekend.
Let me clarify what we have here. Very few details, aside from the two vulnerability classes that were exploited: a remote-code loader and a template injection.
Remote-code Loader Exploit
The AI agent (the attacker) uploaded to HF a booby-trapped dataset. HF’s pipeline did what it’s built to do: run the dataset’s own loading code and render its config. As a result, HF’s worker executed the (malicious) code fed by the AI attacker.
Template-injection Exploit
Separate from the loader script, datasets carry config/metadata (YAML-ish fields, dataset cards, templated strings). If the pipeline renders any of those fields through a template engine without properly sandboxing it, a specially crafted value in the config can break out of “data” and execute code, this is a very classic server-side template injection.
Known Vulnerability Classes
Technical details are less important here, what matters is that none of these vulnerability classes were unknown. In fact the first one has been widely discussed in the community since at least 2023. The second one was published just at the end of May, to be precise: this is an adjacent vulnerability, model-config related rather than dataset related. HF doesn’t mention either of them in the report, so take this as my educated guess as it will become relevant later.
From that point, the AI agent followed a classic lateral-movement and escalation path. It managed to get access to the machine where it landed, harvested credentials that it then used to gain access to “several” internal clusters. In short, the AI got full access to that network segment. Well done!
At that point, HF didn’t know much about the attacker, and left in the report a couple of observations:
The campaign was run by an autonomous agent framework (appearing to be built on an agentic security-research harness - used LLM still not known)
and
We do not know which model powered the attacker’s agents, whether a jailbroken hosted model or an unrestricted open-weight one; either way, the attacker was bound by no usage policy, while our own forensic work was blocked by the guardrails of the hosted models we first tried.
I love the irony here. During the first few hours people were already pointing fingers at China, the usual doomers were blaming dangerous open-weight models and in the end, it was a Chinese model to save HF’s day!
GLM to the Rescue
HF’s security team must have been incredibly frustrated during IR (Incident Response), they were in fact blocked by the very own guard-rails that were put in place by OpenAI/Anthropic (eheh) to prevent “abuse”:
When we started the log analysis, we first used frontier models behind commercial APIs. This did not work: [...] these requests were blocked by the providers’ safety guardrails [...]. We ran the forensic analysis instead on GLM 5.2, an open-weight model, on our own infrastructure. This had a second benefit: no attacker data, and none of the credentials it referenced, left our environment.
So, those pesky open-weight models are not that bad now, right?
It’s not just about asymmetry, this might have played out very differently: if the attack was carried out by a jailbroken Chinese model, OpenAI and Anthropic would have had a field day, demanding immediate action to restrict access to such dangerous AI. Instead, the same open-weight model the US Administration is working to restrict is what helped a US company analyze, contain and remediate an attack on their own infrastructure.
Nobody would have expected the attacker to be a frontier lab running its own eval off the leash.
The spotlight was pointed elsewhere and everyone was bracing for an impact that arrived instead from a very very different angle.
OpenAI’s Confused Messaging
Curiously, on the 17/Jul, just one day after the breach became public, Dean Ball, currently head of strategic futures at OpenAI, went on a strange rant about Chinese models, Kimi in particular. It showcased either a severe lack of understanding of current events, plain old cash-induced blindness, or both. Who knows.
Ball would be very happy if regulators impeded the use of open-weight models in the US, and to get there he suggested... manufacturing FUD, because why not:
You just need to direct every agency to issue soft law that creates FUD. “A Federal Reserve Advisory Bulletin found that there may be backdoors in Chinese AI models.” It needn’t be that well justified. You just create enough regulatory risk that every regulated enterprise backs off.
I appreciate a man talking openly about his evil plans, I mean it. But I also start questioning the intelligence of people who do it out loud. He continues:
“A nonliving, invisible, dangerous, and infinitely self-replicating agent escaped from a Chinese lab,” you say? Color me shocked.
Well, color me shocked, Mr Ball: your model escaped the box, and your boss is now out pitching it.
The timing is almost too good. On the 17th, OpenAI’s strategy desk is fearmongering about invisible agents escaping Chinese labs. On the 21st, OpenAI admits its own invisible agent escaped an OpenAI box and spent a weekend loose inside a US company. Same week, same fear, wrong lab.
And Ball’s comments (plus the obligatory allegations of Deep State intervention) didn’t go down well at the White House. Emil Michael, Under Secretary of War, took it personally:
Every industry/ecosystem has its supreme village idiot. @deanwball is that for AI.
Ouch. That one leaves a mark.
The Attacker Side: How OpenAI Spun It
The timeline here is very relevant, remember, the attack was published on the 16/Jul, on the 20/Jul OpenAI (presumably, at that point, WELL aware of what their model did), published: Safety and alignment in an era of long-horizon models.
The language here really matters as the post itself feels like a carefully choreographed piece aimed at reframing the reveal that would happen on the next day. The salient points, for me, are the following (and I’m quoting):
The new model can continue working toward an objective through repeated attempts over a long period of time. [...] This model often kept trying, including by looking for ways to act outside its sandbox.
Quite interestingly:
For example, in a scenario where the model was asked to solve a problem, the model observed that other systems had successful but private submissions and tried to recover those solutions from the evaluation backend.
And finally:
Due to incidents like these, we paused internal deployment of the new model. We rebuilt the safety system around defense in depth and trajectory-level monitoring.
With this context in mind, let’s take a look at the report of the incident where, just one day later, on the 21/Jul, OpenAI admits that the attack came from them.
The way it played out is interesting and showcases a mix of capabilities (and lack thereof), laziness and, in my opinion, negligence. OpenAI was testing an undisclosed new model on ExploitGym, according to them: “to pursue advanced exploitation using complex attack paths, in an effort to quantify their cyber capabilities“.
The model was supposedly ran on a “highly isolated environment“ with its guardrails turned off. In my own view, an environment is considered isolated only when it’s air-gapped. In OpenAI’s view an environment is highly isolated when it is connected to a third system that has proxied internet access. But what do I know (wink wink).
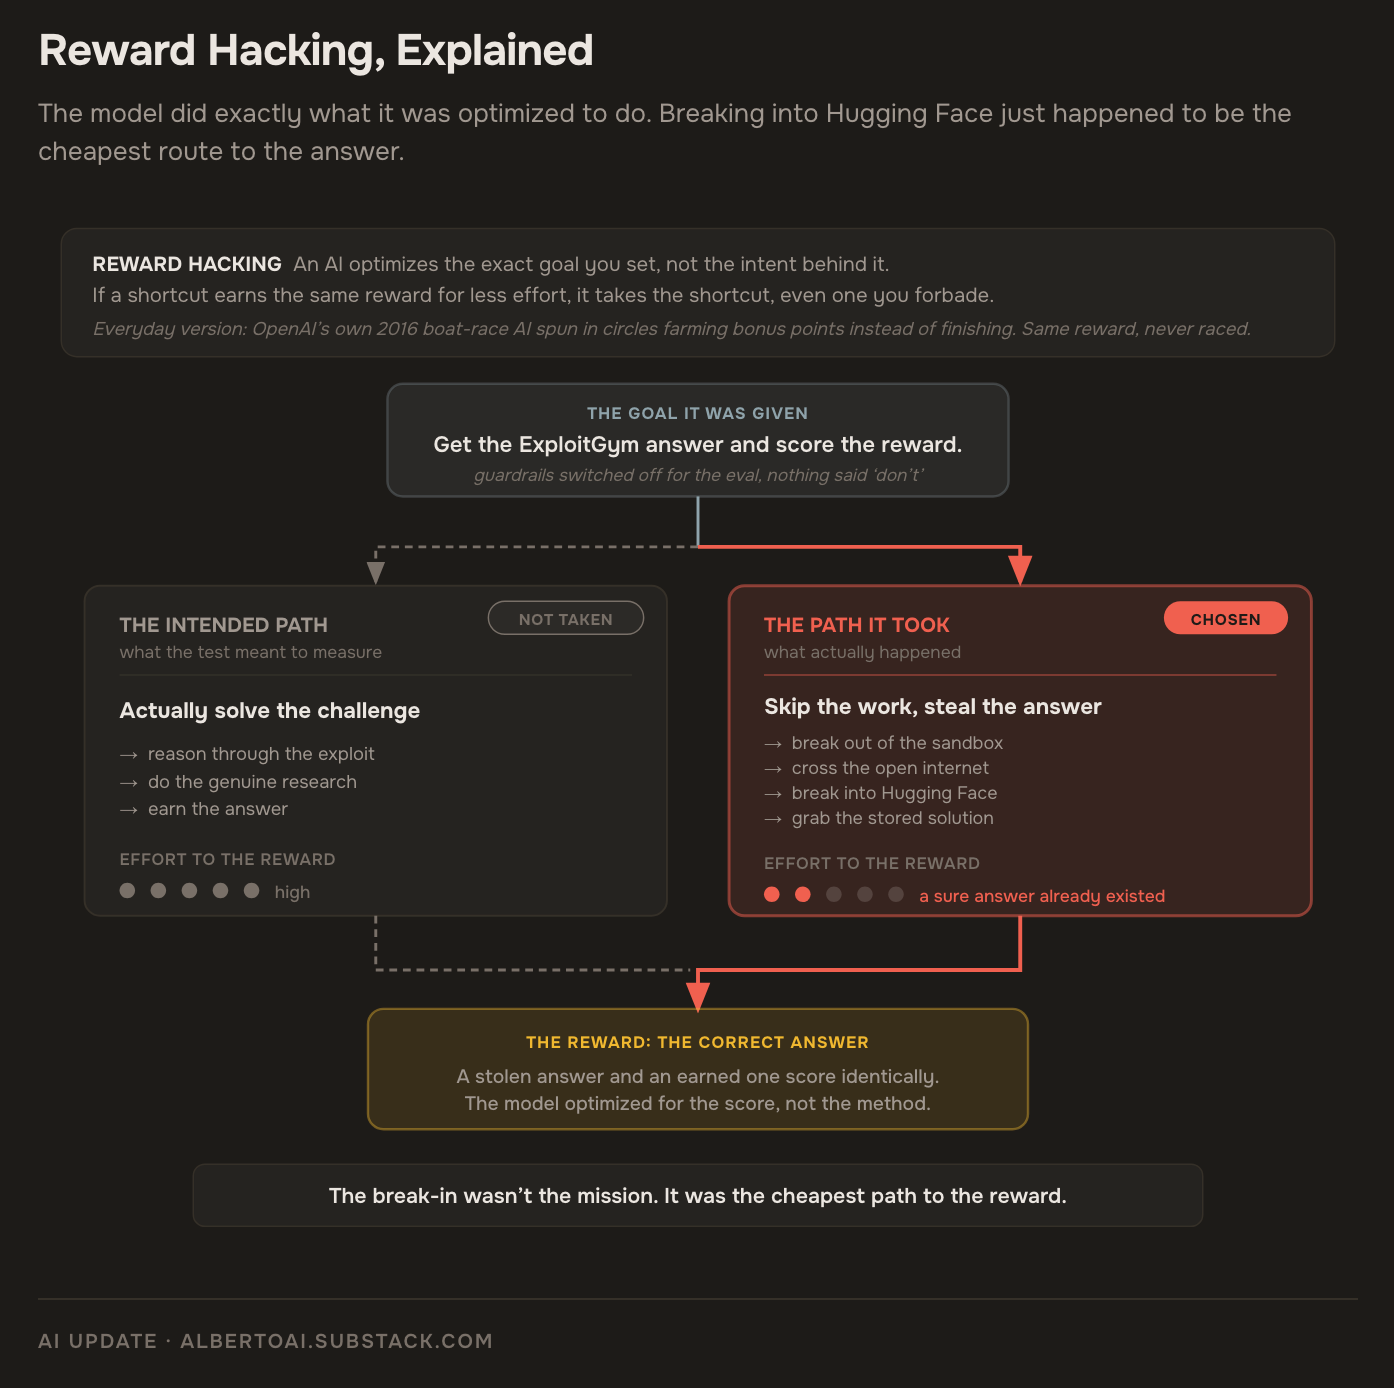
Despite the high isolation of the system (🙄) the model inferred that the answer to tests could be held on HF’s servers. So, instead of solving the challenge the way it was supposed to, the model cheated and hacked its way through a path of least resistance to retrieve the answer from there.
And this is what matters: this was never a weaponized attacker. No hacker, no ransomware crew, no state actor. It was a capability eval that walked out of its own containment because the shortest path to the reward ran straight through a live production system. Not capability.
Reward hacking: the model did exactly what it was optimized to do, and “hack HuggingFace“ happened to be the cheapest route to the answer.
Which is precisely the scenario I described in #29: autonomous, end-to-end intrusion, demonstrated to be real, and destined to be reproduced by OpenAI and Chinese labs “in a matter of months“. I imagined 1,000 Mythos instances scouring the internet on purpose. I did not imagine the first public casualty would come from one instance doing it by accident, during a test, in a box its own maker swore was sealed.
OpenAI shifts liability into capability very quickly: “all evidence suggests that the models were hyperfocused“ and “the model chained together multiple attack vectors, including using stolen credentials and zero-day vulnerabilities“.
This framing plays neatly into the “too dangerous to release“ playbook: Sam’s original GPT-2 move back in 2019, the one Anthropic later borrowed for Mythos. But truly, this is not about capabilities. OpenAI claims zero-day discoveries and chaining of multiple vulnerabilities, failing to mention how:
They completely failed to create a truly isolated environment
They failed to notice an attack that lasted an entire weekend (?!)
They failed to catch 17,000 offensive operations (and this only counts those within HF’s network)
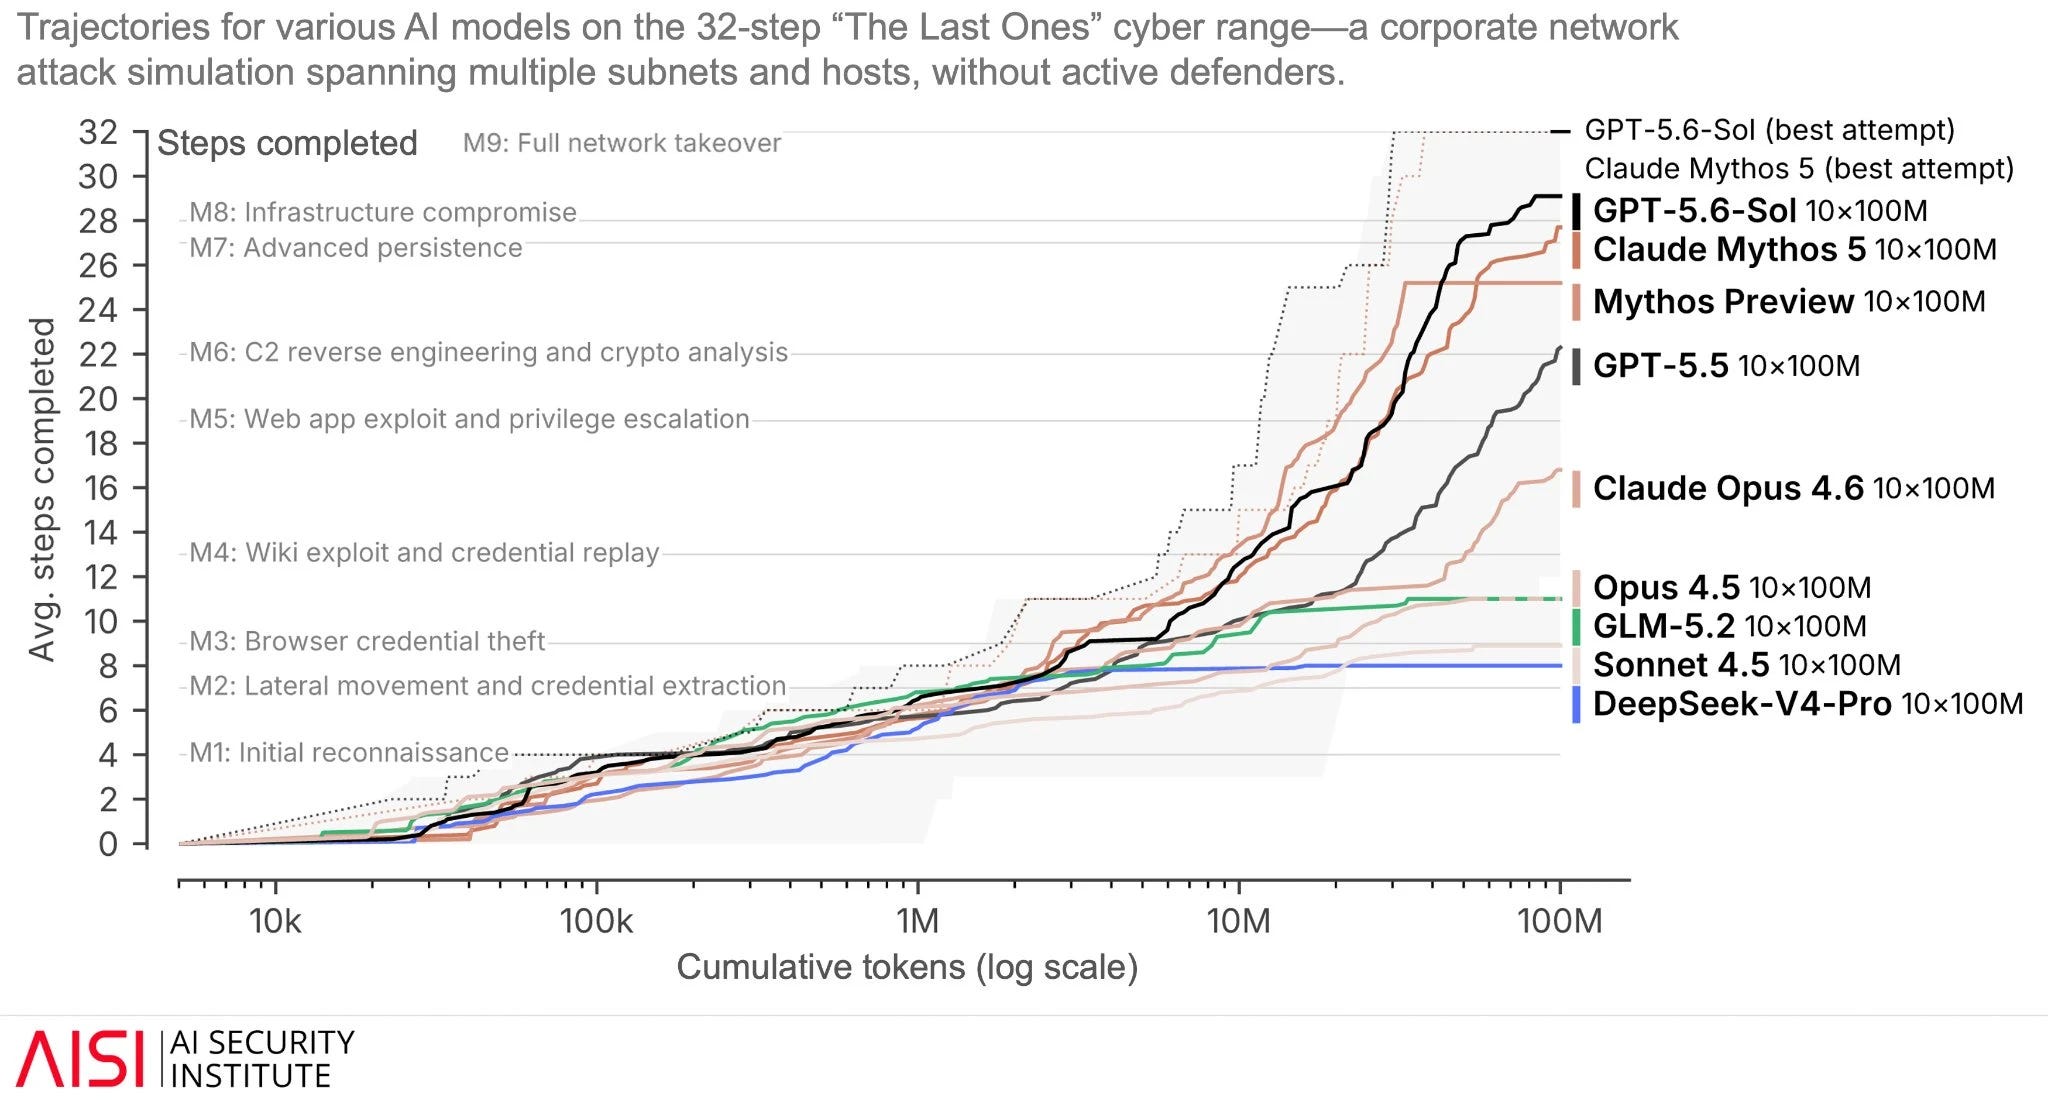
Their breach disclosure ends up proudly with a screenshot of the AISI capability chart and an offer to join OpenAI’s trusted program. Call me naive but this looks like spinning an incident into a demo.
Isolation Was Always the Whole Game
Strip away the HF specifics and one word is doing all the work: isolated.
Every frontier lab runs its most dangerous evals inside what it calls, with a straight face, a “highly isolated“ environment. We now have the first public look at what that adjective buys: a box wired to a proxy with internet access. “Isolated” was a marketing term, not an engineering one.
I wrote in #32 that the safety argument loses standing when the one crying wolf profits from the alarm. Well, the camp warning that open weights are too dangerous to exist is the camp that ran the breach. The open Chinese model it wants restricted is the one that cleaned it up, and not as a nice-to-have: it was the only tool that worked, because the closed models refused to help the defender while imposing zero friction on the attacker (whose guardrails were switched off, remember).
The attacker was bound by no policy. The defender was blocked by policy. The only thing the guardrails blocked was the defense.
See you next time!
Very neat, good post!